
Biography
I am a PhD student in the Department of Computer Science and Engineering at the Chinese University of Hong Kong, advised by Prof. Eric Lo.
My current research focuses on agentic AI systems, with an emphasis on enabling reliable semantic data processing at scale. I also work on LLM infrastructure, particularly agent-aware serving through scheduling and KV cache management.
Before CUHK, I received my bachelor’s degree from Huazhong University of Science and Technology (HUST) and was an exchange student in the Department of Electrical Engineering and Computer Sciences (EECS) at the University of California, Berkeley.
Beyond Research
Beyond research, I am drawn to things that reward patience and refinement. Music has long been one of them: I enjoy listening, singing, and spending time with the piano, erhu, bamboo flute, guitar, and a few other instruments. It remains, for me, both a quiet discipline and a lasting source of joy.
CV
Research Projects
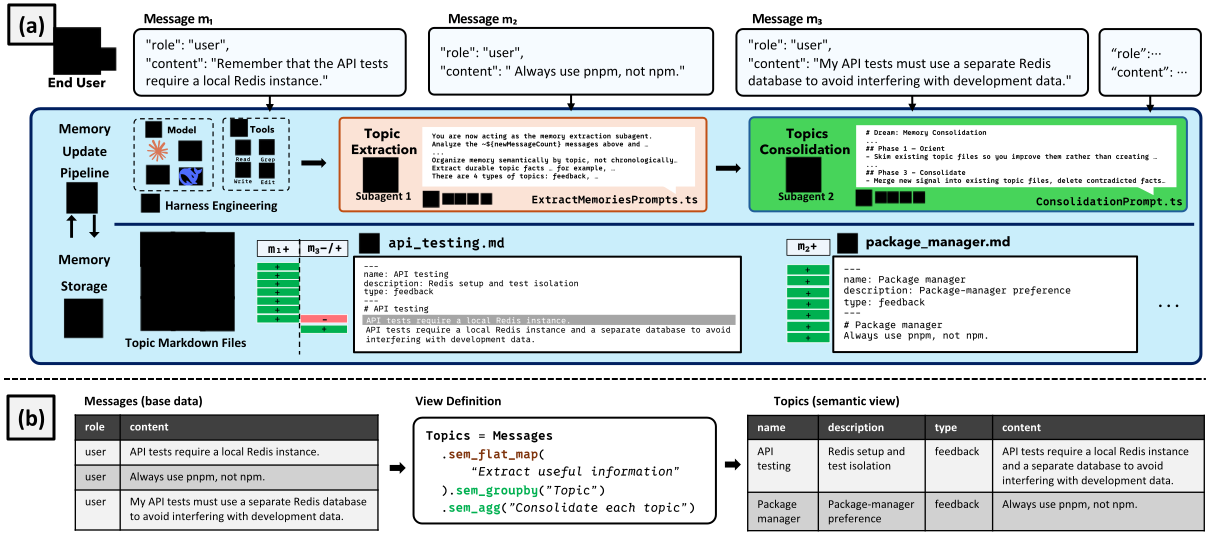
Declarative Long-Horizon Agent Memory Maintenance
Under review at VLDB 2027
A declarative framework that treats long-horizon agent memory as materialized semantic views over interactions. It automatically derives incremental semantic queries for memory maintenance from user-defined views, separating what agents retain from how their memories are maintained and the computation is optimized.
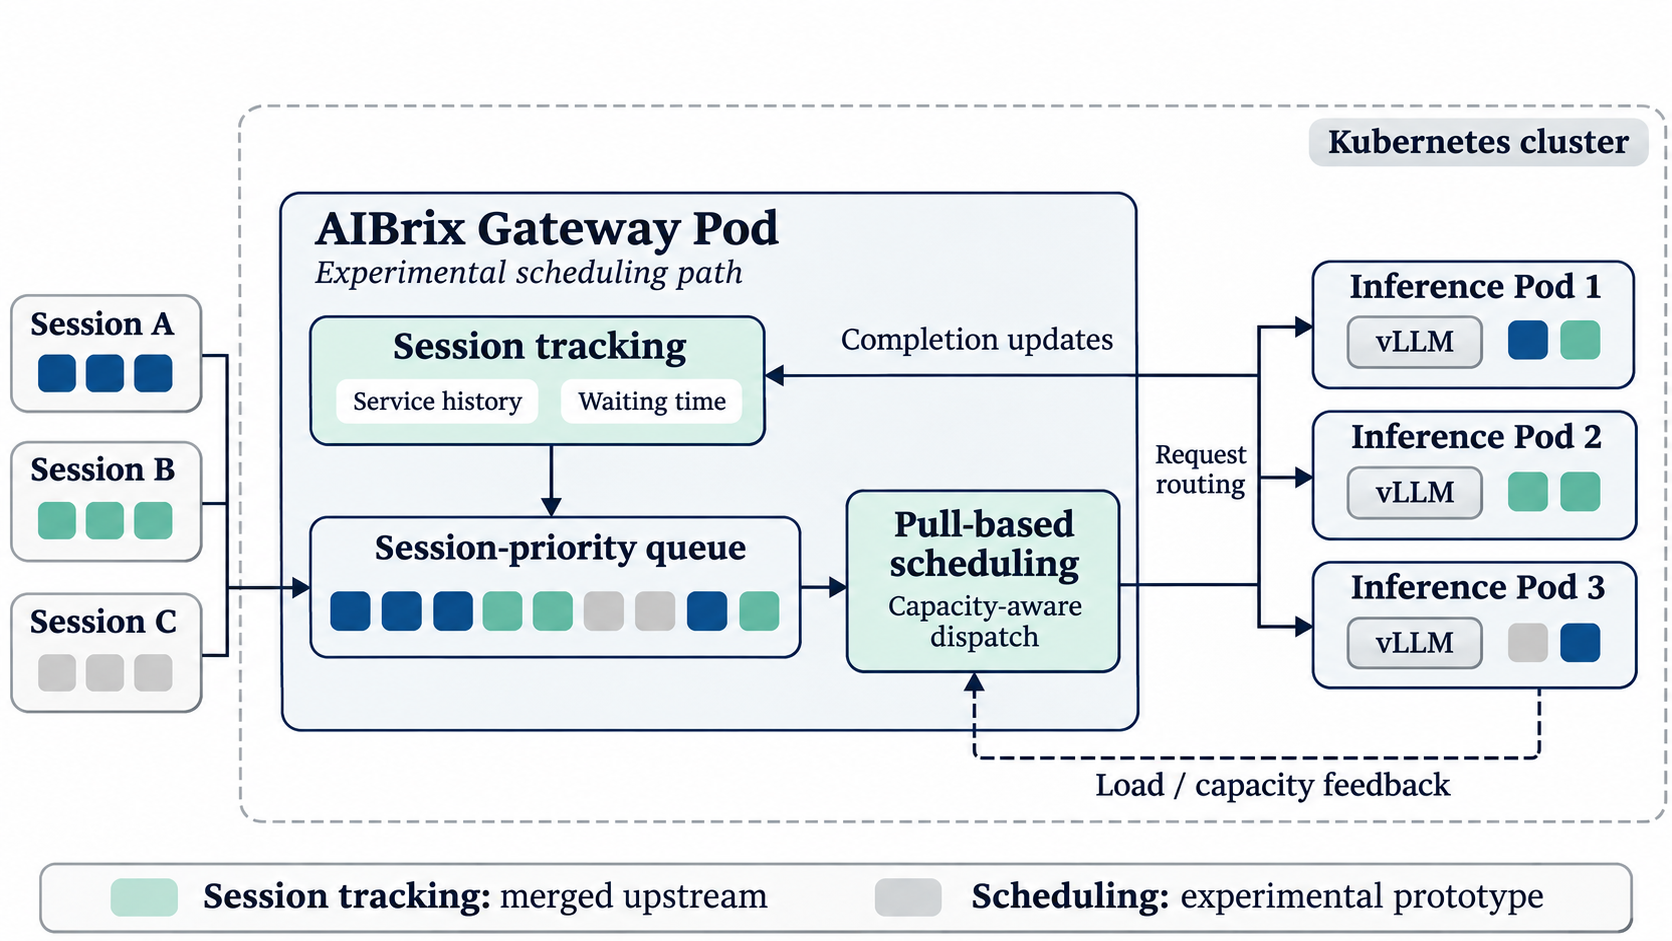
AIBrix: Session-Aware LLM Serving
Upstream contribution / Experimental scheduling
Developed session tracking and prototyped pull-based scheduling for agentic workloads in AIBrix, combining session-level priorities with capacity-aware dispatch. Session-state management was merged upstream; the scheduling prototype remains an internal exploration.
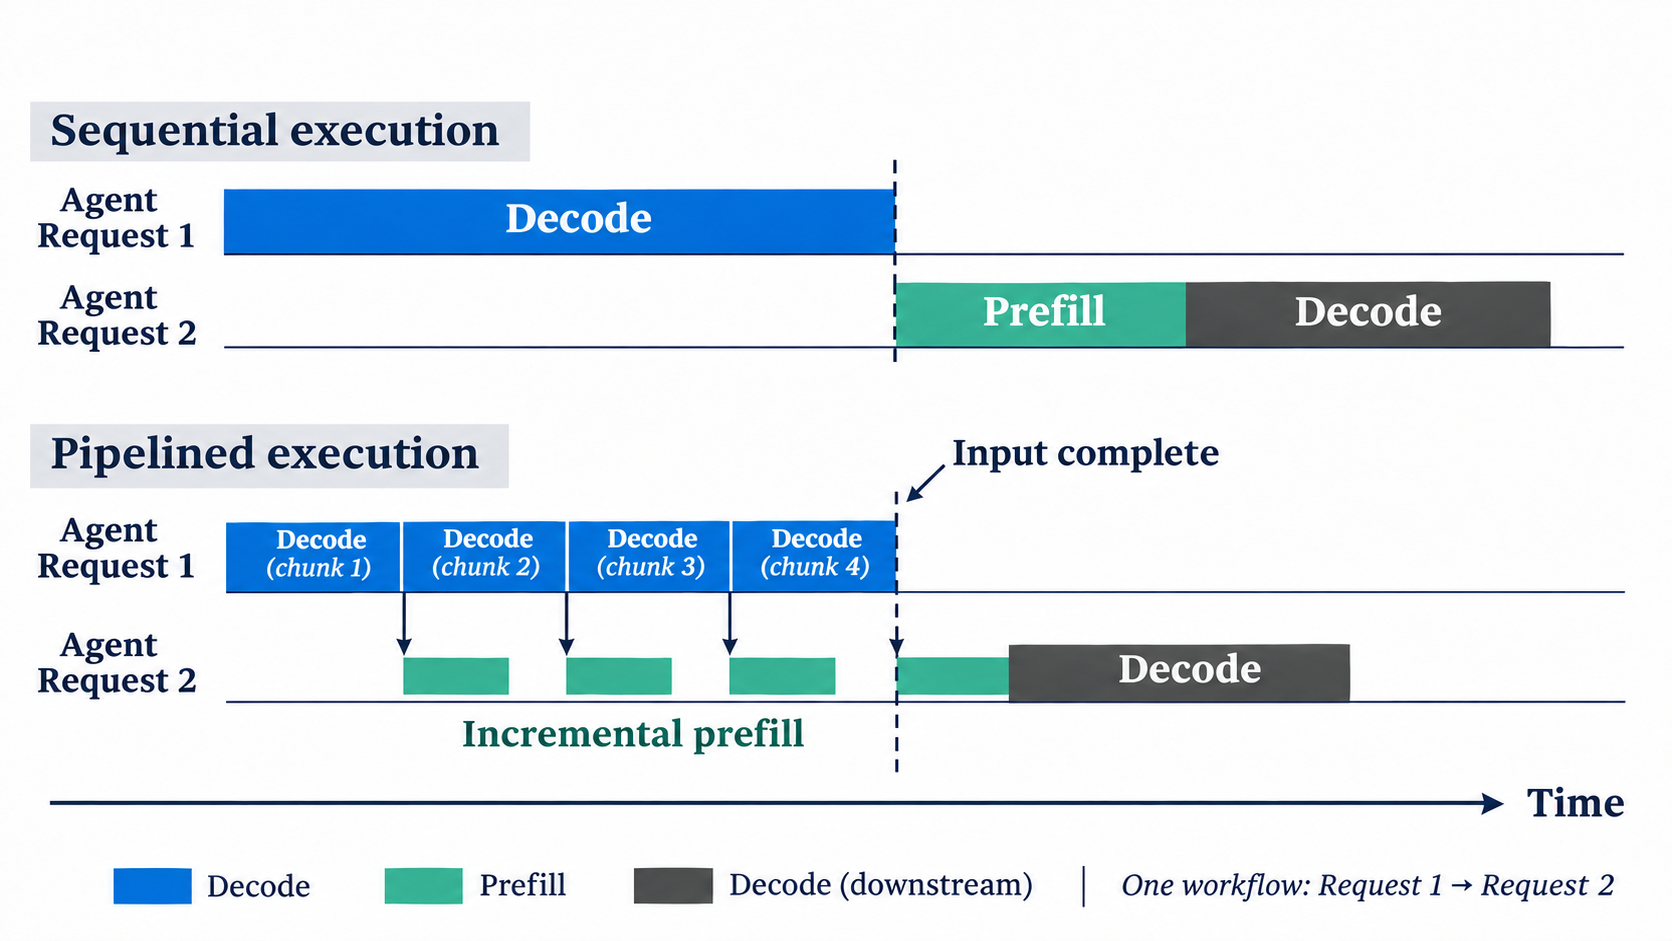
SDServe: Pipelining Dependent LLM Requests under Agentic Workloads
Research prototype / On hold
Explored overlapping upstream decoding with downstream prefill in dependent LLM calls. The vLLM-based prototype accepts incremental prompt input, allowing downstream computation to begin before upstream generation completes.
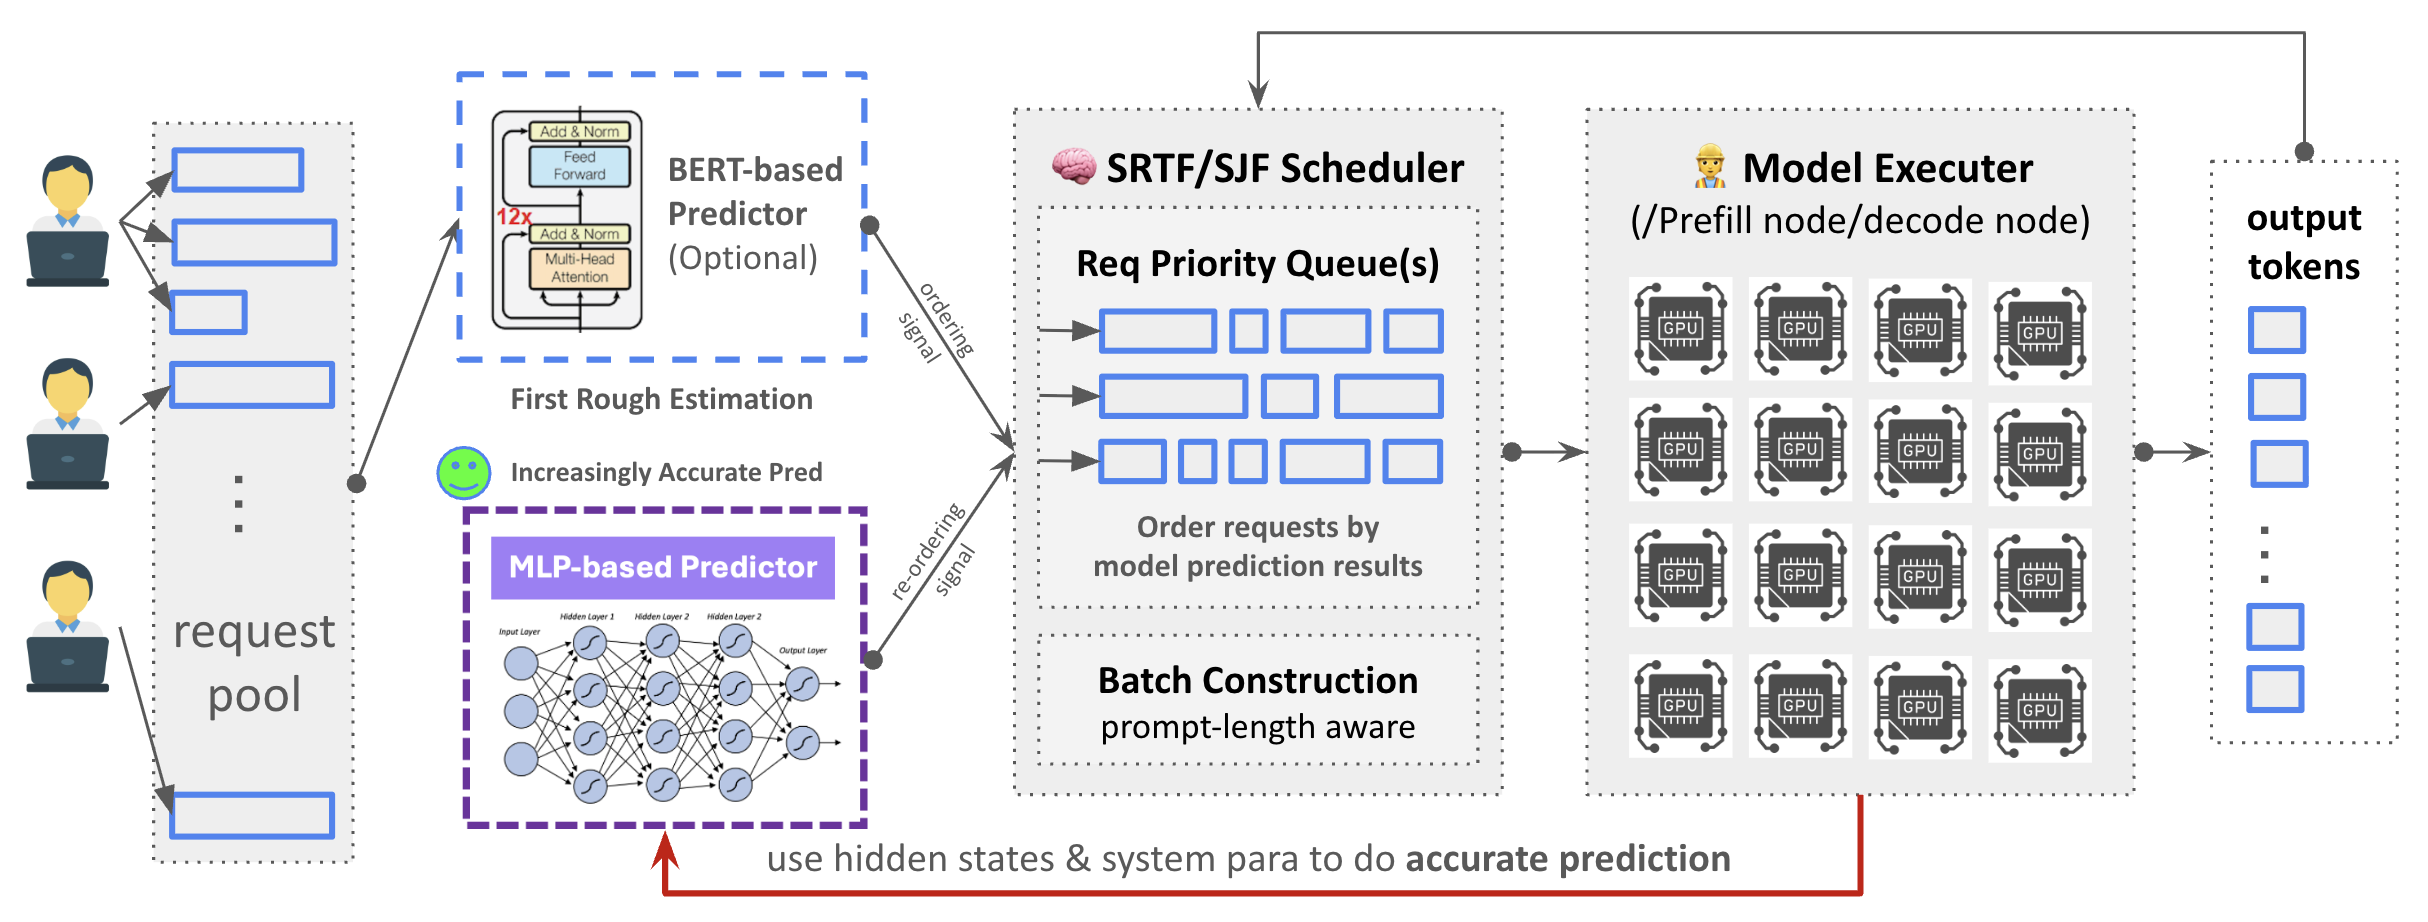
PrediServe: Preemptive LLM Scheduling with Length Prediction
Research prototype / Predictor code available
Explored preemptive LLM scheduling guided by remaining-generation-length predictions. The predictor combines model hidden states with decoding parameters to account for variation across generation settings.
Teaching
Teaching Assistant, The Chinese University of Hong Kong
- AIST4020: Agentic AI and LLM Serving (Fall 2026)
- CSCI3250: Computers and Society (Spring 2026)
- CSCI3170: Introduction to Database Systems (Fall 2025, Fall 2024)
- CSCI3150: Introduction to Operating Systems (Spring 2025)
- CMSC5735: Advanced Topics in Cloud Computing (Spring 2025)